The PostgreSQL vacuum evolution of the last ten years can be stated in one sentence: between PostgreSQL 9.6 and PostgreSQL 19, vacuum stopped being a slow, memory-capped, whole-table scanner and became a scheduled, eager, parallel and I/O-aware subsystem, yet the single most common cause of bloat in production is still exactly what it was in 2016. Vacuum cannot remove what the oldest open snapshot might still need.
This paper traces that decade release by release, explains the mechanism behind each change, and turns it into a measurement playbook with runnable SQL, a Python audit script and version-aware configuration guidance. It is written for platform owners and senior DBAs who run PostgreSQL fleets across mixed major versions. Feature claims were checked against the official PostgreSQL release notes on 5 November 2026; PostgreSQL 19 was at release candidate stage at that date, so treat its items as subject to final release.
Key findings from ten years of PostgreSQL vacuum evolution
- Wraparound risk was tamed in three steps: the freeze map (9.6), the failsafe (14) and eager freezing of all-visible pages (18).
- Throughput limits were mostly defaults, not code. The 2 ms autovacuum cost delay (12) and the end of the 1 GB dead-tuple memory ceiling (17) changed more fleets than any tuning guide.
- Index bloat moved from cure to prevention through B-tree deduplication (13) and bottom-up index deletion (14).
- Space reclamation without an outage finally arrives in core with
REPACK (CONCURRENTLY)in PostgreSQL 19. - The xmin horizon did not move. Long transactions, abandoned slots, orphaned prepared transactions and standby feedback still defeat every improvement above.
The two jobs vacuum has always done
PostgreSQL implements MVCC by writing new tuple versions instead of updating in place. Vacuum therefore has two independent obligations, and the PostgreSQL vacuum evolution is best read as progress on each. The first is reclamation: tuples whose deleting transaction is older than every live snapshot are dead, and their space, along with the index entries pointing to them, must be made reusable. The second is freezing: transaction IDs are 32 bits wide, so tuples old enough to be visible to everyone must be marked frozen before the XID counter wraps around and makes them appear to be in the future.
Most operational confusion comes from treating these as one problem. Reclamation failure produces bloat and degraded scans. Freezing failure produces wraparound pressure, aggressive anti-wraparound vacuums and, at the limit, a cluster that refuses new XIDs. The PostgreSQL vacuum evolution described here improved both, but at different times and through different mechanisms.

Figure 1. PostgreSQL vacuum evolution mapped onto a single VACUUM pass: the release that changed each phase is shown in brackets.
A pass scans the heap, pruning pages and collecting dead tuple identifiers. When the identifier store fills, or the scan ends, vacuum removes matching entries from every index, then marks the heap line pointers unused. Only trailing empty pages are returned to the operating system. Everything else becomes free space inside the file, which is why ordinary vacuum controls bloat growth but rarely shrinks a bloated table.
A decade of PostgreSQL vacuum evolution at a glance

Figure 2. The PostgreSQL vacuum evolution timeline, 9.6 to 19.
We group the decade into four eras. Each era solved the bottleneck the previous one exposed, which is the most useful way to reason about what a given major version will and will not do for you.
Era 1 of the PostgreSQL vacuum evolution (9.6 to 12): stop rereading frozen data
PostgreSQL 9.6 added an all-frozen bit to the visibility map. Before it, an anti-wraparound vacuum had to read every page of a table, including pages that had not changed in years. With the freeze map, aggressive vacuums skip pages already marked all-frozen, turning a full read of a multi-terabyte table into a read of the pages modified since the last freeze. The same release introduced pg_stat_progress_vacuum, the first time operators could see which phase a vacuum was in without reading logs. Both changes set the direction for the rest of the PostgreSQL vacuum evolution: do less redundant work, and make the work observable.
9.6 also introduced old_snapshot_threshold, an attempt to let vacuum ignore very old snapshots. It never matured; PostgreSQL 17 removed it. That history matters, because it is the only serious attempt in the decade to attack the xmin horizon directly, and it failed on correctness and performance grounds.
PostgreSQL 10 made hash indexes WAL-logged and crash-safe, which brought their vacuuming into the same reliability envelope as B-tree. PostgreSQL 11 allowed one VACUUM command to list several tables and introduced vacuum_cleanup_index_scale_factor to skip B-tree cleanup scans on insert-only tables, a setting later ignored from 13.3 and removed in 14.
PostgreSQL 12 delivered the most consequential default change of the decade: autovacuum_vacuum_cost_delay fell from 20 ms to 2 ms. On the same cost limit that is a tenfold increase in the I/O autovacuum is allowed to spend. By the end of Era 1, the PostgreSQL vacuum evolution had made autovacuum fast enough by default for most mid-sized databases. Version 12 also added the TRUNCATE and INDEX_CLEANUP options with matching storage parameters, SKIP_LOCKED, and REINDEX CONCURRENTLY, the first in-core way to rebuild a bloated index without blocking writes.
Era 2 of the PostgreSQL vacuum evolution (13 to 15): parallelism and index bloat prevention
PostgreSQL 13 added the PARALLEL option, letting a manual VACUUM process a table's indexes with parallel workers. It also closed a long-standing gap: insert-only tables never accumulated dead tuples, so autovacuum never visited them, their pages were never set all-visible and index-only scans degraded. The new autovacuum_vacuum_insert_threshold and autovacuum_vacuum_insert_scale_factor make inserts trigger vacuum too. B-tree deduplication arrived in the same release; indexes carried across pg_upgrade need a REINDEX to benefit.
PostgreSQL 14 is where wraparound stopped being an emergency procedure. vacuum_failsafe_age and vacuum_multixact_failsafe_age let a vacuum that is approaching wraparound drop cost-based delay and skip non-essential index work to finish the freeze. Bottom-up index deletion lets B-tree inserts remove expired entries before splitting a page, which is the single largest structural reduction in index bloat for update-heavy tables in the PostgreSQL vacuum evolution. INDEX_CLEANUP gained a default of auto, skipping index vacuuming when very few entries are removable, and the default vacuum_cost_page_miss was reduced to reflect modern storage.
PostgreSQL 15 moved cumulative statistics into shared memory, removing the statistics collector process and the lag it introduced into autovacuum's view of table activity. Vacuum also became more aggressive about advancing the oldest frozen and multixact IDs, and log_autovacuum_min_duration now defaults to 10 minutes, so slow autovacuums are logged out of the box. Era 2 of the PostgreSQL vacuum evolution thus moved the bottleneck from correctness and safety to memory and I/O.
Era 3 of the PostgreSQL vacuum evolution (16 to 18): memory, I/O and eager vacuum freezing
PostgreSQL 16 added the BUFFER_USAGE_LIMIT option and the vacuum_buffer_usage_limit setting, giving direct control over the ring buffer vacuum uses; PostgreSQL 17 raised its default to 2 MB. Version 16 also introduced opportunistic page freezing during ordinary vacuums, made autovacuum honour delay-setting changes at each block rather than each relation, and added pg_stat_io, which finally separates vacuum I/O from client I/O.
PostgreSQL 17 replaced the flat array of dead tuple identifiers with a compact radix-tree store, the TidStore. Two consequences matter operationally. Vacuum is no longer silently limited to 1 GB of memory when maintenance_work_mem or autovacuum_work_mem are set higher, and the same memory now holds far more identifiers, so very large tables need fewer index passes. Pruning and freezing were also combined into more compact WAL records, reducing vacuum's replication footprint. The progress view columns were renamed accordingly: max_dead_tuple_bytes, dead_tuple_bytes and num_dead_item_ids.
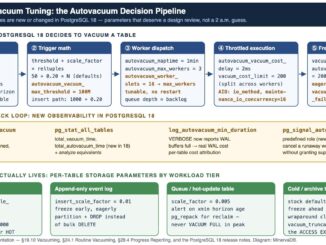
PostgreSQL 18 brought three changes we consider essential for large fleets. Asynchronous I/O, selected with io_method, lets vacuum's heap scan queue reads rather than issue them one at a time. Eager vacuum freezing, governed by vacuum_max_eager_freeze_failure_rate, lets ordinary vacuums freeze some all-visible pages early, spreading freeze work instead of concentrating it in a single aggressive vacuum. And autovacuum_vacuum_max_threshold caps the dead-tuple trigger for very large tables, so a billion-row table is no longer waiting for 200 million dead tuples under the default 20 percent scale factor.
Version 18 also added autovacuum_worker_slots, which allows autovacuum_max_workers to change on reload up to that ceiling, timing columns such as total_autovacuum_time in pg_stat_all_tables, cost-delay timing through track_cost_delay_timing, and vacuum_truncate as a server-level setting. Era 3 is the part of the PostgreSQL vacuum evolution that most changes capacity planning. We cover version 18 tuning in depth in our guide to PostgreSQL 18 vacuum tuning.
Era 4 of the PostgreSQL vacuum evolution (19): prioritisation and online reclamation
PostgreSQL 19 addresses the two gaps operators have complained about longest. First, ordering: autovacuum gains a scoring system that decides which tables to process first, tuned by autovacuum_vacuum_score_weight, autovacuum_vacuum_insert_score_weight, autovacuum_freeze_score_weight, autovacuum_multixact_freeze_score_weight and autovacuum_analyze_score_weight, and exposed through pg_stat_autovacuum_scores. Autovacuum can also use parallel workers for indexes, controlled by autovacuum_max_parallel_workers and the per-table autovacuum_parallel_workers parameter.
Second, reclamation. The new REPACK command unifies VACUUM FULL and CLUSTER, which remain for compatibility, and REPACK (CONCURRENTLY) rebuilds a table without holding an access-exclusive lock for the duration, using logical decoding to capture concurrent changes. A new max_repack_replication_slots setting budgets the slots it needs. Smaller but important changes complete the picture: ordinary query scans can now set pages all-visible, wraparound warnings start at 100 million remaining XIDs instead of 40 million, multixact members are now 64-bit, and the progress view reports started_by and mode. With version 19, the PostgreSQL vacuum evolution reaches the point where scheduling and space reclamation, not raw speed, are the main levers.
What the PostgreSQL vacuum evolution did not change: the xmin horizon
Every improvement above makes vacuum faster or smarter at removing tuples it is allowed to remove. None of them changes which tuples it is allowed to remove, and no release in the PostgreSQL vacuum evolution has changed that rule. That boundary is the global xmin horizon, the oldest transaction ID that any snapshot in the system might still need.

Figure 3. The xmin horizon, the constant across the whole PostgreSQL vacuum evolution.
Transaction ID wraparound and PostgreSQL bloat share this root cause. In our incident work, the first question on any bloat or wraparound escalation is therefore not which version or which settings, but what is holding the horizon. The query below answers it in one pass and is safe to run on a production primary.
-- PostgreSQL vacuum evolution playbook, step 1: what is holding the xmin horizon?
-- Read-only. Works on PostgreSQL 10 and later.
SELECT
    'session'                              AS holder_type,
    pid::TEXT                              AS holder,
    usename || ' / ' || COALESCE(application_name, '') AS detail,
    state,
    AGE(backend_xmin)                      AS xmin_age,
    NOW() - xact_start                     AS xact_duration
FROM pg_stat_activity
WHERE backend_xmin IS NOT NULL
UNION ALL
SELECT
    'replication_slot',
    slot_name,
    slot_type || ' active=' || active::TEXT,
    NULL,
    GREATEST(AGE(xmin), AGE(catalog_xmin)),
    NULL
FROM pg_replication_slots
WHERE xmin IS NOT NULL OR catalog_xmin IS NOT NULL
UNION ALL
SELECT
    'prepared_xact',
    gid,
    owner || ' / ' || database,
    NULL,
    AGE(transaction),
    NOW() - prepared
FROM pg_prepared_xacts
UNION ALL
SELECT
    'standby_feedback',
    application_name,
    client_addr::TEXT,
    state,
    AGE(backend_xmin),
    NULL
FROM pg_stat_replication
WHERE backend_xmin IS NOT NULL
ORDER BY xmin_age DESC NULLS LAST
LIMIT 20;
The remedies are organisational more than technical: idle_in_transaction_session_timeout and transaction_timeout (PostgreSQL 17 and later) for sessions, alerting on inactive slots and setting max_slot_wal_keep_size, monitoring pg_prepared_xacts, and treating hot_standby_feedback on reporting replicas as a deliberate trade against primary bloat.
Measuring PostgreSQL bloat the way the evolution now allows
Statistical bloat estimates from catalog queries are useful for triage but can mislead by tens of percent on wide or TOAST-heavy rows. For decisions that cost a maintenance window, we measure. The pgstattuple extension's approximate function reads only pages not marked all-visible, which, thanks to the visibility map improvements in this PostgreSQL vacuum evolution, makes it practical on large tables.
-- PostgreSQL vacuum evolution playbook, step 2: measure heap and index bloat.
-- pgstattuple_approx skips all-visible pages; pgstatindex reads the whole index,
-- so run it off-peak on large indexes.
CREATE EXTENSION IF NOT EXISTS pgstattuple;

SELECT
    table_len                                   AS heap_bytes,
    ROUND(approx_tuple_percent::NUMERIC, 1)     AS live_pct,
    ROUND(dead_tuple_percent::NUMERIC, 1)       AS dead_pct,
    ROUND(approx_free_percent::NUMERIC, 1)      AS free_pct
FROM pgstattuple_approx('public.orders'::REGCLASS);

SELECT
    index_size,
    avg_leaf_density,
    leaf_fragmentation
FROM pgstatindex('public.orders_pkey');
A high free_pct with low dead_pct means vacuum is keeping up but the table once grew and never shrank; that is a reclamation problem for REPACK, not a tuning problem. A high dead_pct means vacuum is falling behind or is blocked by the horizon. A B-tree avg_leaf_density well below the default fillfactor of 90 indicates index bloat that REINDEX CONCURRENTLY will recover.
Is autovacuum keeping up?
-- PostgreSQL vacuum evolution playbook, step 3: autovacuum pressure per table.
-- n_ins_since_vacuum needs PostgreSQL 13+; total_autovacuum_time needs 18+
-- (remove that column on older versions).
SELECT
    relid::REGCLASS                                       AS table_name,
    n_live_tup,
    n_dead_tup,
    ROUND(100.0 * n_dead_tup / NULLIF(n_live_tup + n_dead_tup, 0), 1) AS dead_pct,
    n_ins_since_vacuum,
    last_autovacuum,
    autovacuum_count,
    ROUND(total_autovacuum_time / 1000.0, 1)              AS autovacuum_seconds_total
FROM pg_stat_user_tables
ORDER BY n_dead_tup DESC
LIMIT 25;
Transaction ID wraparound headroom
-- PostgreSQL vacuum evolution playbook, step 4: transaction ID wraparound headroom.
-- Compare against autovacuum_freeze_max_age (default 200 million) and
-- vacuum_failsafe_age (default 1.6 billion, PostgreSQL 14+).
SELECT
    datname,
    AGE(datfrozenxid)         AS xid_age,
    MXID_AGE(datminmxid)      AS mxid_age,
    ROUND(100.0 * AGE(datfrozenxid) / 2147483647, 2) AS pct_to_wraparound
FROM pg_database
ORDER BY xid_age DESC;

SELECT
    c.oid::REGCLASS                AS table_name,
    AGE(c.relfrozenxid)            AS xid_age,
    MXID_AGE(c.relminmxid)         AS mxid_age,
    PG_SIZE_PRETTY(PG_TOTAL_RELATION_SIZE(c.oid)) AS total_size
FROM pg_class AS c
WHERE c.relkind IN ('r', 'm', 't')
ORDER BY AGE(c.relfrozenxid) DESC
LIMIT 20;
Watching a running vacuum on PostgreSQL 17 and 18
-- PostgreSQL vacuum evolution playbook, step 5: live progress.
-- Column names below are PostgreSQL 17+. delay_time needs PostgreSQL 18 with
-- track_cost_delay_timing = on.
SELECT
    p.pid,
    p.relid::REGCLASS                                     AS table_name,
    p.phase,
    ROUND(100.0 * p.heap_blks_scanned / NULLIF(p.heap_blks_total, 0), 1) AS scanned_pct,
    PG_SIZE_PRETTY(p.dead_tuple_bytes)                    AS dead_tid_memory,
    PG_SIZE_PRETTY(p.max_dead_tuple_bytes)                AS dead_tid_budget,
    p.num_dead_item_ids,
    p.index_vacuum_count,
    p.indexes_processed || '/' || p.indexes_total         AS indexes,
    ROUND(p.delay_time / 1000.0, 1)                       AS delay_seconds
FROM pg_stat_progress_vacuum AS p;
If delay_seconds dominates elapsed time, autovacuum is throttled by cost accounting rather than by I/O, and raising the cost limit is justified. If index_vacuum_count exceeds one on PostgreSQL 17 or later, the dead TID budget is too small for that table.
Autovacuum tuning by version: parameters, defaults and reload rules
Autovacuum tuning has to follow the PostgreSQL vacuum evolution, because several defaults and reload rules changed between versions. The table records defaults and our usual starting points for OLTP fleets on modern SSD or NVMe storage. The starting points are illustrative, not prescriptive; we change them only after the measurements above show which constraint is binding.
| Parameter | Default | Typical starting point | Applies | Reload or restart |
|---|---|---|---|---|
| autovacuum_vacuum_cost_limit | -1 (uses vacuum_cost_limit 200) | 1000 to 2000 | All | Reload |
| autovacuum_vacuum_cost_delay | 2 ms (20 ms before 12) | 2 ms | All | Reload |
| autovacuum_max_workers | 3 | 5 to 8 on many-table clusters | All | Restart before 18; reload in 18+ |
| autovacuum_worker_slots | 16 | 16 | 18+ | Restart |
| autovacuum_work_mem | -1 (uses maintenance_work_mem 64 MB) | 512 MB to 2 GB (above 1 GB only helps on 17+) | All | Reload |
| autovacuum_vacuum_max_threshold | 100,000,000 tuples | Lower per table for very large hot tables | 18+ | Reload |
| vacuum_failsafe_age | 1,600,000,000 XIDs | Leave at default | 14+ | Reload |
| autovacuum_freeze_max_age | 200,000,000 XIDs | Raise only with measured freeze throughput | All | Restart |
Server-level changes are applied as below. Per-table settings are where most of the value lies, because a single queue or session table usually accounts for most dead tuples in a database.
-- PostgreSQL vacuum evolution playbook, step 6: autovacuum tuning (reloadable).
-- Current vs proposed:
--   autovacuum_vacuum_cost_limit  -1 (200)  -> 1500
--   autovacuum_work_mem           -1 (64MB) -> 1GB
-- Test on a staging replica of production first; record current values.
SHOW autovacuum_vacuum_cost_limit;
SHOW autovacuum_work_mem;

ALTER SYSTEM SET autovacuum_vacuum_cost_limit = 1500;
ALTER SYSTEM SET autovacuum_work_mem = '1GB';
SELECT pg_reload_conf();

-- Validation: confirm the running values changed and nothing needs a restart.
SELECT name, setting, unit, pending_restart
FROM pg_settings
WHERE name IN ('autovacuum_vacuum_cost_limit', 'autovacuum_work_mem');

-- Rollback: ALTER SYSTEM RESET autovacuum_vacuum_cost_limit;
--           ALTER SYSTEM RESET autovacuum_work_mem; SELECT pg_reload_conf();

-- Per-table: a hot queue table vacuumed at 1 percent churn, not 20 percent.
ALTER TABLE public.job_queue SET (
    autovacuum_vacuum_scale_factor = 0.01,
    autovacuum_vacuum_threshold    = 1000,
    autovacuum_vacuum_cost_limit   = 3000
);
Vacuum freezing strategy after PostgreSQL 18
Before 16, freezing was lazy by design: tuples were frozen only once they crossed vacuum_freeze_min_age, and all-visible pages were skipped until an aggressive vacuum forced a full pass. The result was the familiar sawtooth, quiet for weeks and then a multi-hour anti-wraparound vacuum at the worst possible moment. Opportunistic freezing in 16 and eager vacuum freezing in 18 change the shape of that curve by paying a little freeze cost on every pass. For vacuum freezing, this is the most important behavioural shift in the PostgreSQL vacuum evolution.
Our guidance is to leave vacuum_max_eager_freeze_failure_rate at its default unless measurement says otherwise, and to watch the new pg_class.relallfrozen column against relpages. On append-mostly tables such as event logs and ledgers, a rising frozen fraction between aggressive vacuums is the signal that eager freezing is working. On tables where pages are updated again soon after being frozen, early freezing is wasted work, and lowering the rate for that table is reasonable.
-- PostgreSQL vacuum evolution playbook, step 7: vacuum freezing coverage (18+).
SELECT
    c.oid::REGCLASS                                              AS table_name,
    c.relpages,
    c.relallvisible,
    c.relallfrozen,
    ROUND(100.0 * c.relallfrozen / NULLIF(c.relpages, 0), 1)     AS frozen_pct,
    AGE(c.relfrozenxid)                                          AS xid_age
FROM pg_class AS c
WHERE c.relkind = 'r'
  AND c.relpages > 10000
ORDER BY c.relpages DESC
LIMIT 20;
Reclaiming space: PostgreSQL REPACK and the remediation ladder
Bloat that already exists is not fixed by better vacuuming, which is the practical lesson PostgreSQL bloat teaches at every stage of the PostgreSQL vacuum evolution. We apply a strict ladder, always starting with the least disruptive step that the measurement supports.
- Release the horizon and let vacuum catch up. This stops growth; it does not shrink files.
- Rebuild bloated indexes with
REINDEX CONCURRENTLY(12 and later). - On PostgreSQL 19, rebuild the table with
REPACK (CONCURRENTLY). On 18 and earlier, the open-sourcepg_repackextension fills the same role. - Only in a maintenance window,
VACUUM FULLor plainREPACK, both of which hold an access-exclusive lock throughout.
Online rebuilds still need free disk for a full copy of the table and its indexes, a primary key or replica identity, and enough WAL and replication capacity to absorb the copy. The procedure below writes those checks in as a confirmation gate.
-- PostgreSQL vacuum evolution playbook, step 8: PostgreSQL REPACK
-- (PostgreSQL 19, release candidate at time of writing).
-- CONFIRMATION GATE: do not run until every check below passes and the change
-- ticket records the results. Test on a staging copy of the table first.

-- Check 1: the table has a primary key or replica identity (required for CONCURRENTLY).
SELECT c.relname, c.relreplident,
       EXISTS (SELECT 1 FROM pg_index AS i
               WHERE i.indrelid = c.oid AND i.indisprimary) AS has_primary_key
FROM pg_class AS c
WHERE c.oid = 'public.orders'::REGCLASS;

-- Check 2: table plus indexes size; confirm at least this much free disk.
SELECT PG_SIZE_PRETTY(PG_TOTAL_RELATION_SIZE('public.orders')) AS space_needed;

-- Check 3 (before): record bloat to compare afterwards.
SELECT approx_free_percent, dead_tuple_percent
FROM pgstattuple_approx('public.orders'::REGCLASS);

-- Rebuild online; must run outside a transaction block.
REPACK (CONCURRENTLY, VERBOSE, ANALYZE) public.orders;

-- Validation (after): free and dead percentages should be near zero and the
-- size should have dropped.
SELECT approx_free_percent, dead_tuple_percent
FROM pgstattuple_approx('public.orders'::REGCLASS);
SELECT PG_SIZE_PRETTY(PG_TOTAL_RELATION_SIZE('public.orders')) AS size_after;
On PostgreSQL 18 and earlier, pg_repack provides a dry run, which we always execute first:
# PostgreSQL vacuum evolution, pre-19 path: online table rebuild with pg_repack.
# Dry run first; credentials come from the environment or ~/.pgpass, never inline.
pg_repack --host="${PGHOST}" --username="${PGUSER}" --dbname="${PGDATABASE}" \
          --table=public.orders --dry-run

# Execute only after the dry run and the disk-space check pass.
pg_repack --host="${PGHOST}" --username="${PGUSER}" --dbname="${PGDATABASE}" \
          --table=public.orders --wait-timeout=60
Using the PostgreSQL 19 autovacuum controls
-- PostgreSQL vacuum evolution on 19: see how autovacuum ranks tables, then
-- allow parallel index vacuuming on one wide, heavily indexed table.
SELECT *
FROM pg_stat_autovacuum_scores
LIMIT 20;

SHOW autovacuum_max_parallel_workers;

ALTER TABLE public.orders SET (autovacuum_parallel_workers = 4);
-- Rollback: ALTER TABLE public.orders RESET (autovacuum_parallel_workers);
Automating the audit across a fleet
Fleets running four or five major versions need one audit that adapts to each. The script below connects to every database on a server, reports wraparound headroom, horizon holders and the tables with the most dead tuples, and adds the version 18 timing columns only where they exist.
"""PostgreSQL vacuum evolution audit: wraparound, horizon and dead tuples.

Requires: psycopg 3 (pip install "psycopg[binary]")
Environment: PGHOST, PGPORT, PGUSER, PGPASSWORD (or ~/.pgpass), PGSSLMODE
Read-only: issues SELECT statements only.
"""
import os

import psycopg

# PostgreSQL vacuum evolution thresholds
XID_WARN = 500_000_000      # well below the 1.6 billion failsafe default
HORIZON_WARN = 50_000_000   # an xmin this old is almost certainly a problem


def connect(dbname):
    return psycopg.connect(dbname=dbname, application_name="vacuum_audit",
                           autocommit=True)


def list_databases():
    with connect(os.environ.get("PGDATABASE", "postgres")) as conn:
        rows = conn.execute(
            "SELECT datname FROM pg_database "
            "WHERE datallowconn AND NOT datistemplate ORDER BY datname"
        ).fetchall()
    return [r[0] for r in rows]


def audit(dbname):
    with connect(dbname) as conn:
        version = conn.info.server_version // 10000
        # PostgreSQL vacuum evolution: timing columns exist only on 18 and later
        xid_age = conn.execute(
            "SELECT AGE(datfrozenxid) FROM pg_database WHERE datname = current_database()"
        ).fetchone()[0]
        horizon = conn.execute(
            "SELECT MAX(AGE(backend_xmin)) FROM pg_stat_activity "
            "WHERE backend_xmin IS NOT NULL"
        ).fetchone()[0] or 0
        timing = ", ROUND(total_autovacuum_time / 1000.0) AS av_seconds" if version >= 18 else ""
        top = conn.execute(
            "SELECT relid::REGCLASS::TEXT, n_dead_tup, last_autovacuum" + timing +
            " FROM pg_stat_user_tables ORDER BY n_dead_tup DESC LIMIT 5"
        ).fetchall()
    return version, xid_age, horizon, top


if __name__ == "__main__":
    for db in list_databases():
        version, xid_age, horizon, top = audit(db)
        flags = []
        if xid_age >= XID_WARN:
            flags.append(f"XID age {xid_age:,}")
        if horizon >= HORIZON_WARN:
            flags.append(f"session xmin age {horizon:,}")
        status = "ATTENTION: " + "; ".join(flags) if flags else "ok"
        print(f"[{db}] PostgreSQL {version}: {status}")
        for row in top:
            print("    ", row)
Upgrade implications for platform owners
For a fleet still on 13 or earlier, the upgrade to 17 or 18 is itself the largest vacuum improvement available, because it collects most of the PostgreSQL vacuum evolution in one step: failsafe, bottom-up deletion, shared-memory statistics, the TidStore and, on 18, eager freezing and asynchronous I/O. Three upgrade details deserve attention. B-tree indexes created before 13 need a REINDEX to use deduplication. The PostgreSQL 17 progress column renames break dashboards that query max_dead_tuples or num_dead_tuples. And PostgreSQL 18 vacuums inheritance children by default, with the new ONLY option restoring the old behaviour.
For PostgreSQL 19, the newest step in the PostgreSQL vacuum evolution, we recommend the usual discipline: validate on staging after general availability and the first minor release, then roll out REPACK (CONCURRENTLY) as a replacement for external rebuild tooling table by table, with the confirmation gate above.
Limits of this analysis
We have not published throughput or bloat-reduction percentages for these releases, because they depend on row width, update pattern, index count and storage; any single number would mislead. The starting points in the tuning table are illustrative. PostgreSQL 19 behaviour is described from its release candidate release notes and could change before final release. Managed services such as Amazon RDS, Aurora, Cloud SQL, AlloyDB and Azure Database for PostgreSQL may restrict some settings or extensions. Every change described here should be tested before it is applied to production, and backed by a tested backup and disaster recovery posture.
Frequently asked questions
What is the most important change in the PostgreSQL vacuum evolution?
For wraparound safety, the 9.6 freeze map combined with the 14 failsafe. For everyday throughput, the 12 change to a 2 ms autovacuum cost delay and the 17 removal of the 1 GB dead tuple memory ceiling.
Which version should we target given the PostgreSQL vacuum evolution?
For production fleets today, PostgreSQL 17 or 18. Together they deliver most of the PostgreSQL vacuum evolution, including TidStore, eager freezing and asynchronous I/O, with mature minor releases. Plan PostgreSQL 19 once it is generally available and has had its first minor release.
Does VACUUM remove PostgreSQL bloat?
Ordinary vacuum makes dead space reusable and returns only trailing empty pages to the operating system. Existing bloat inside a file is removed by VACUUM FULL, REPACK or an online rebuild tool, and index bloat by REINDEX CONCURRENTLY.
Does PostgreSQL REPACK replace pg_repack?
On PostgreSQL 19, REPACK (CONCURRENTLY) provides in-core online table rebuilds, which covers the main use of pg_repack. On 18 and earlier, pg_repack remains the practical option.
Why is autovacuum running but dead tuples are not going down?
Almost always the xmin horizon. A long or idle-in-transaction session, an inactive replication slot, an orphaned prepared transaction or standby feedback is holding back the oldest snapshot. Run the horizon query in this article first.
Where can I read the official changes?
The PostgreSQL 19 release notes, the PostgreSQL 18 release notes and the PostgreSQL 17 release notes are the primary sources for the recent part of this PostgreSQL vacuum evolution.
How MinervaDB helps
MinervaDB is a vendor-neutral database infrastructure company trusted by 900+ enterprises. Our PostgreSQL consulting team applies the lessons of the PostgreSQL vacuum evolution in bloat and wraparound assessments, version upgrade programmes and autovacuum tuning for fleets from 9.6 to 19, and our 24x7 PostgreSQL support responds to wraparound and bloat incidents under a 15-minute S1 SLA.
Running this in production?
MinervaDB provides PostgreSQL Consulting, PostgreSQL Support and PostgreSQL Remote DBA with 24x7 coverage and a 15-minute S1 response. Talk to an engineer.